Home / Trending Programs 2026 / Data Engineering & Modern Cloud Platforms
Distributed Data Systems • 2026 Specialization

Data Engineering & Cloud Platforms

Architect Petabyte-Scale Lakehouses, Streaming Ingestion & Modern dbt/Snowflake Stacks

Master the infrastructure powering enterprise analytics and AI. Build distributed lakehouse architectures with Apache Spark & PySpark, real-time Kafka event streaming, dbt modular transformations, Snowflake analytical data warehouses, and Apache Airflow DAG orchestration.
7 Months Duration
320+ Hrs Live Mentor Labs
1-on-1 Mentor Guidance
Spark Cluster Cloud Lab Access
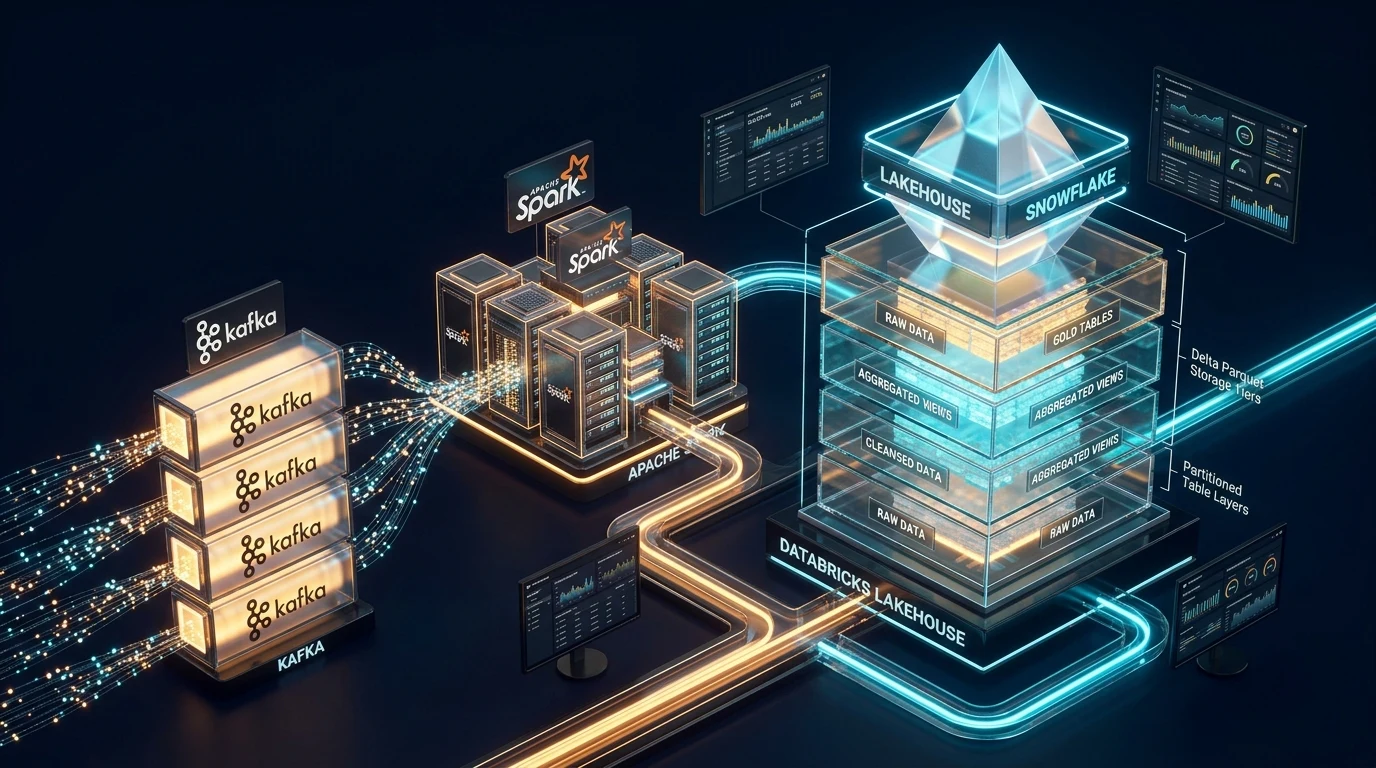
Data Engineering and Modern Cloud Platforms 3D Lakehouse Visual
Upcoming 2026 Batch Admissions
Limited 25 Seats • Weekend & Evening Batches

Get Expert Course Guidance

Speak with a Principal Architect & get a customized roadmap, syllabus, and 0% EMI plans.

+91
100% Confidential 15-Min Fast Callback 1-on-1 Career Mentorship
🎓
Dual Certification Industry Recognized Certification
💻
Distributed Spark Lab Kafka & Snowflake Lakehouse Access
👥
1:1 Technical Mentorship Architecture Reviews by Lead Engineers
💼
1-on-1 Career Mentorship Dedicated Interview Prep & Hiring Partner Drives
DATA INFRASTRUCTURE REALITIES

Built for Massive Data Volumes & Real-Time Speed

Modern enterprise applications generate trillions of records. Companies are replacing legacy brittle ETL scripts with modern Medallion lakehouses, modular dbt data modeling, and streaming architectures.

01

Medallion Lakehouse Architecture

Organize messy raw telemetry into clean Bronze, Silver, and Gold tiers using Delta Lake and Apache Iceberg. Guarantee ACID transactions, schema enforcement, and time-travel rollbacks on cloud object storage.

02

Distributed PySpark & Kafka Streaming

Process massive multi-terabyte datasets across distributed worker clusters. Master Catalyst query optimization, broadcast hash joins, memory tuning, and real-time Kafka event stream processing.

03

Modern Analytics Engineering with dbt & Snowflake

Adopt software engineering best practices for data: modular SQL models in dbt, automated data contracts, zero-copy cloning in Snowflake, and automated Airflow DAG orchestration.

COMPREHENSIVE SYLLABUS

Industry-Aligned Practical Modules

A comprehensive curriculum engineered by Principal Data Architects. Progress from cloud storage fundamentals to distributed Spark computing, modern dbt/Snowflake analytics, and real-time streaming pipelines.

MODULE 01 • 7 WEEKS

Advanced SQL, Python Data Structures & Cloud Storage

Establish high-performance query optimization and architect scalable cloud object storage lake foundations.

MODULE 1.1
Advanced Analytical SQL & Execution Plans
Complex window functions, CTEs, recursive queries, EXPLAIN cost plans, partitioning, and indexing strategies.
MODULE 1.2
Python for Data Engineering & Async I/O
Memory-efficient generators, multiprocessing, asyncio API scraping, and type-annotated data pipelines.
MODULE 1.3
Cloud Object Storage (AWS S3 & Azure ADLS)
S3 bucket policies, lifecycle transitions, IAM role federation, multi-part uploads, and blob storage patterns.
MODULE 1.4
Columnar Formats: Parquet, ORC & Avro
Row-oriented vs columnar storage, dictionary encoding, snappy compression, and partitioning best practices.
HANDS-ON LIVE PROJECT: High-Throughput Ingestion Framework Ingesting Multi-Source Telemetry into Partitioned Snappy Parquet on AWS S3.
MODULE 02 • 7 WEEKS

Distributed Computing with Apache Spark & Delta Lake

Process terabyte-scale datasets across distributed clusters, optimize execution plans, and implement ACID table formats.

MODULE 2.1
Apache Spark Architecture & Catalyst Optimizer
Driver/Executor topology, DAG execution engine, Catalyst optimizer, Tungsten execution, and wide vs narrow transformations.
MODULE 2.2
PySpark DataFrame API & Advanced Joins
Broadcast hash joins, shuffle sort merge joins, handling data skew with salting, and custom User Defined Functions (UDFs).
MODULE 2.3
Delta Lake ACID Transactions & Time Travel
Delta transaction log, ACID guarantees, schema evolution, VACUUM operations, and time-travel query rollbacks.
MODULE 2.4
Apache Iceberg Table Format & Partition Evolution
Iceberg metadata tree, hidden partitioning, schema evolution, and querying multi-engine tables with Trino/Presto.
HANDS-ON LIVE PROJECT: Distributed PySpark Engine Processing 60M+ Records with Broadcast Joins, Delta ACID Guarantees, and Zero Data Loss.
MODULE 03 • 7 WEEKS

Modern Analytics Engineering with dbt, Snowflake & Databricks

Build enterprise dimensional models, version-controlled SQL pipelines, and zero-maintenance cloud data warehouses.

MODULE 3.1
Snowflake Cloud Data Warehouse Architecture
Multi-cluster shared data architecture, virtual warehouses, micro-partitioning, clustering keys, and zero-copy cloning.
MODULE 3.2
Snowflake Security, Data Sharing & Snowpark
Dynamic data masking, row access policies, secure data sharing, and building Python pipelines inside Snowpark.
MODULE 3.3
dbt Core Project Architecture & Modular SQL
Source staging, dimensional modeling (Kimball), incremental models, ref() dependencies, and Jinja macros.
MODULE 3.4
Data Testing, Data Contracts & Documentation
Automated uniqueness/not-null tests, dbt expectations, schema contract enforcement, and automated docs generation.
HANDS-ON LIVE PROJECT: Production dbt & Snowflake Analytical Data Mart with Automated Data Contracts, Lineage Graphs, and CI Validation.
MODULE 04 • 7 WEEKS

Real-Time Streaming, Airflow Orchestration & DataOps

Construct low-latency streaming pipelines with Kafka, orchestrate enterprise DAG workflows with Airflow, and enforce DataOps quality gates.

MODULE 4.1
Apache Kafka & Event Stream Ingestion
Brokers, partition keys, consumer group offset commits, Kafka Connect connectors, and Schema Registry (Avro).
MODULE 4.2
Spark Structured Streaming & Watermarking
Micro-batch processing, continuous processing, event-time windowing, watermarking for late data, and stream-to-Delta sinks.
MODULE 4.3
Apache Airflow 2.9 Production DAG Orchestration
Task dependencies, TaskFlow API, dynamic task mapping, Celery/Kubernetes executors, and custom operators.
MODULE 4.4
DataOps: Great Expectations, OpenLineage & CI/CD
Automated data profiling, Great Expectations validation checkpoints, OpenLineage end-to-end telemetry, and GitHub Actions CI.
HANDS-ON LIVE PROJECT: Real-Time Streaming Lakehouse Orchestrated by Airflow with Kafka Streaming, Spark Sinks, and Great Expectations Quality Gates.
LAKEHOUSE PORTFOLIO

Industry Data Engineering Live Projects

Build enterprise-scale data infrastructure projects that prove hands-on mastery over distributed processing, cloud warehouses, and streaming pipelines.

LIVE PROJECT 01 • REAL-TIME STREAMING

Petabyte Real-Time Clickstream Streaming Lakehouse

An end-to-end clickstream analytics engine ingesting millions of user events per second into a Delta Lake Medallion architecture with sub-minute query latency.

INGESTION TIER: Apache Kafka + Schema Registry + AWS S3
COMPUTE ENGINE: Spark Structured Streaming with Watermarking
TABLE FORMAT: Delta Lake Bronze, Silver, Gold with ACID writes
SERVING TIER: Databricks SQL • Sub-second aggregation queries
LIVE PROJECT 02 • ANALYTICS ENGINEERING

Financial Transaction Audit Pipeline with dbt & Snowflake

An enterprise financial ledger pipeline executing incremental transformations across 80M+ daily records with strict data contract enforcement and zero-copy cloning.

DATA WAREHOUSE: Snowflake Multi-Cluster Warehouse
TRANSFORMATIONS: dbt Core Incremental Models + Jinja Macros
DATA GOVERNANCE: Dynamic Data Masking + Row-Level Security
CI VALIDATION: Automated schema tests running on pull requests
LIVE PROJECT 03 • DATAOPS & ORCHESTRATION

Enterprise Data Quality & Lineage Engine with Airflow

A robust automated data orchestration platform executing complex multi-cloud DAG dependencies, validating data SLAs, and publishing lineage graphs.

ORCHESTRATOR: Apache Airflow 2.9 (Celery / Kubernetes Executor)
QUALITY GATES: Great Expectations Automated Checkpoints
METADATA LINEAGE: OpenLineage Integration • Marquez Dashboard
ALERT DISPATCH: Slack Webhooks • Automated SLA failure triage
ENTERPRISE TOOLCHAIN

Master the Modern Data Stack

Learn the exact distributed engines, cloud warehouses, and orchestration frameworks utilized by leading data teams worldwide.

COMPUTE
Apache Spark 3.5
Distributed big data processing, DAG optimization, and shuffle tuning
LANGUAGES
PySpark
Python API for large-scale distributed DataFrame transformations
EVENT STREAM
Apache Kafka
Distributed event streaming, partition balancing, and Schema Registry
CLOUD WAREHOUSE
Snowflake
Multi-cluster compute, zero-copy cloning, and time-travel querying
TRANSFORMATION
dbt Core
Modular analytics engineering, incremental models, and schema testing
ORCHESTRATION
Apache Airflow
DAG workflow scheduling, TaskFlow API, and distributed executors
LAKEHOUSE
Delta Lake
ACID transaction guarantees on cloud storage with schema evolution
OPEN FORMAT
Apache Iceberg
High-performance table format for massive petabyte data stores
PLATFORM
Databricks
Unified analytics workspace, Delta Live Tables, and MLflow
CLOUD INFRA
AWS S3 & EMR
Elastic cloud storage, IAM policies, and on-demand compute clusters
DATA QUALITY
Great Expectations
Automated data profiling, validation assertions, and docs
CONTAINERS
Docker
Local reproducible container stacks for Kafka, Airflow, and Spark
ADMISSIONS • 2026 SPECIALIZATION

Apply for Data Engineering & Cloud Platforms

Submit your details to receive the comprehensive 28-week curriculum breakdown, cloud lab sandbox details, and connect with our senior career counsellors.

🔒 Verified Data Privacy: Your details are encrypted and used strictly for senior career counsellorsling. Zero spam guaranteed.
COMMON QUESTIONS

Frequently Asked Questions

Direct answers regarding eligibility, hands-on cloud resources, curriculum depth, and career assistance.

How does Data Engineering differ from Data Analytics or Data Science?+
Data Analysts build reports and BI dashboards; Data Scientists train machine learning models. Data Engineers build and maintain the foundational pipelines, distributed storage, and streaming infrastructure that collect, clean, and deliver petabyte-scale data.
What are the batch timings and training delivery modes?+
Available as live interactive online classes nationwide, as well as hands-on classroom batches at our Noida Sector 62 campus. We offer Weekday morning/evening batches and Weekend batches for working IT professionals.
Do I need prior experience with Apache Spark or AWS?+
No prior big data experience is required. We start Module 01 with advanced SQL optimization, database indexing, and Python data structures before transitioning to Apache Spark, PySpark, and distributed streaming with Kafka.
Why is dbt and Snowflake central to this curriculum?+
dbt (data build tool) and Snowflake have become the enterprise standard for cloud data lakehouses. They enable modular SQL modeling, automated testing, and CI/CD version control for modern data teams in India and globally.
What kind of Career Guidance & Interview Prepis provided for Data Engineering roles?+
Our dedicated career office provides resume optimization highlighting production data pipelines, 1-on-1 mock interviews on SQL, Spark, and pipeline architecture, and direct referrals to hiring partners in Noida, Gurgaon, Bangalore, and Hyderabad.
What real-world projects will I build for my portfolio?+
You build end-to-end production pipelines including real-time e-commerce streaming analytics with Kafka and PySpark, an automated financial lakehouse using Snowflake & dbt, and automated DAG scheduling using Apache Airflow.

📊 AWS Cloud Solutions Architect & Multi-Cloud DevOps (CKA/Terraform) in India (Noida, Delhi NCR, Bangalore, Mumbai, Pune, Hyderabad & Online) — 2026 Fees, Batch Schedule, Syllabus & Placement Report

Compare 4Achievers' updated 2026 fee structure, 0% No-Cost EMI plans, upcoming weekday/weekend cohorts, hands-on module breakdown, and top hiring companies across Noida Sector 62, Bangalore Whitefield/ORR, Hyderabad HITEC City, Pune Hinjewadi, Mumbai BKC & Gurgaon Cyber City.

1. 2026 Course Fee Structure, Duration & 0% EMI Options in India (Noida, Delhi NCR, Bangalore, Mumbai, Pune, Hyderabad & Online)

Training TrackDuration2026 Course Fee0% No-Cost EMILab & Placement Support
Self-Paced + Cloud SandboxFlexible (1 Yr Access)🔒 Request Self-Paced Fee PDF →AvailableRecorded Labs + Resume Review
Live Instructor-Led (Pan-India Live Online & Campus Hybrid) ⭐ Most Popular4.5 Months (180+ Hours Live AWS/Azure Production Labs)📥 Get 2026 Live Batch Fee →0% No-Cost EMI & Up to 30% Scholarship Available24/7 Live Sandbox + Unlimited Mock Interviews
100% Placement-Assisted Job Bootcamp4.5 Months (180+ Hours Live AWS/Azure Production Labs) + Internship🎓 Check Job Bootcamp Fee →Up to 12 Months 0% EMIDedicated Placement Cell + 6-Week Industrial Letter

2. Upcoming November 2026 Batch Schedule (India (Noida, Delhi NCR, Bangalore, Mumbai, Pune, Hyderabad & Online))

Batch TypeStart DateClass Timings (IST)ModeSeat Availability
Weekday Regular Cohort06 Nov 2026 (Mon–Fri)10:00 AM – 12:00 PMClassroom & Live Online🔥 Only 4 Seats Left
Weekend Working-Pro Cohort08 Nov 2026 (Sat–Sun)11:00 AM – 02:00 PMClassroom & Live Online✅ Open (5 Seats Left)
Evening Fast-Track Cohort11 Nov 2026 (Mon–Fri)08:00 PM – 10:00 PMLive Interactive Online✅ Open for Enrollment

3. 2026 Updated Syllabus Modules & Tool Stack (AWS (EC2, EKS, S3, VPC, IAM, Lambda), Microsoft Azure (AZ-104), Linux, Docker, Kubernetes (CKA), Terraform, Ansible, Jenkins, GitHub Actions, ArgoCD & Prometheus)

ModuleCore Topics, Practical Labs & Deliverables
Module 1Linux System Administration, Networking Fundamentals & Bash Shell Scripting Automation
Module 2AWS Solutions Architect (SAA-C03): VPC Peering, EC2 Auto-Scaling, S3, RDS & IAM Security
Module 3CI/CD Release Engineering: Git Workflows, Jenkins Declarative Pipelines & GitHub Actions
Module 4Containerization & Orchestration: Docker Multi-Stage Builds & Kubernetes (CKA / AWS EKS)
Module 5Infrastructure as Code (IaC) & Config Management: Terraform Modules & Ansible Playbooks
Module 6GitOps with ArgoCD, DevSecOps Scanning & Observability (Prometheus, Grafana & ELK Stack)

4. Top Hiring Companies & 2026 Salary Packages in India (Noida, Delhi NCR, Bangalore, Mumbai, Pune, Hyderabad & Online)

Local Tech CorridorsTop Hiring MNCs & GCCsFresher (0–2 Yrs)Mid-Level (2–5 Yrs)Senior / Lead (5+ Yrs)
Noida Sector 62, Bangalore Whitefield/ORR, Hyderabad HITEC City, Pune Hinjewadi, Mumbai BKC & Gurgaon Cyber CityTCS, Infosys, HCLTech, Accenture, Deloitte USI, Walmart Global Tech, JPMorgan, Barclays & Jio Platforms₹6.0 LPA – ₹10.5 LPA₹12.0 LPA – ₹22.0 LPA₹24.0 LPA – ₹45.0 LPA

🎓 Download 2026 AWS Cloud Solutions Architect & Multi-Cloud DevOps (CKA/Terraform) Syllabus PDF, Fee Brochure & Book Free Demo Class

Enter your WhatsApp number below to receive the complete module-wise PDF, scholarship discount coupon, and free demo link for India (Noida, Delhi NCR, Bangalore, Mumbai, Pune, Hyderabad & Online):

📌 Page Quick Jump: 1. Overview & Highlights 2. 2026 Curriculum & Labs 3. Fee Structure & ROI 4. Career Mentorship & FAQs
Explore Official Noida Campus & Live Batches →
📊 Data Engineering And Modern Cloud Platforms (Noida, Delhi NCR, Mumbai, Bangalore & Online) — 2026 Updated Batch, Fee & Lab Overview
Training Track (2026) Duration & Mode Hands-On Cloud / ERP Labs Fee & Scholarship Options Career Mentorship
Fast-Track Certification 8–10 Weeks (Weekday / Weekend) 24/7 Cloud Sandbox + 2 Live Projects 0% Interest Monthly EMI Available 1-on-1 Resume & Mock Interviews
Executive Master Program 14–20 Weeks (Classroom & Live Online) 24/7 Enterprise Lab + 4 Capstone Projects Up to 50% Merit Scholarship + 0% EMI 1-on-1 Architect Mentorship & Portfolio
🚀 Explore Related 2026 Career Programs, City Training Hubs & Interview Resources
Flagship Cloud & ERP Courses
Top Courses in Noida
2026 Certification Cost & Papers
Trending Skill & Career Tracks
View All 6,400+ Programs Directory →