High Demand Specialization 2026

LLM Engineering & RAG
Master Advanced RAG Pipelines, Vector Databases & Enterprise Search.
Get Placed in Top MNCs.

Master LLM Engineering & RAG with LlamaIndex, LangChain, Vector Databases (Pinecone, Qdrant, Chroma), Hybrid Search, Re-Ranking, and RAG evaluation. 100% placement assurance.
4.9/5 Rating (1.8k+ Reviews)
90+ Hours Live Hands-on
15+ RAG Tools Modern Stack
Production Capstone Labs
100% Placement Support
Global Certification
Alumni Alumni Alumni Alumni
48,500+ Placed Alumni •
4.9/5 Google Reviews
Scholarship Challenge
Test Your Skills, Unlock Your Discount
Take a 5-min quick test & unlock up to 30% scholarship discount!
Assessment Test
Build
Autonomous
Systems
Live Labs
& Real Data
100% Placement Support
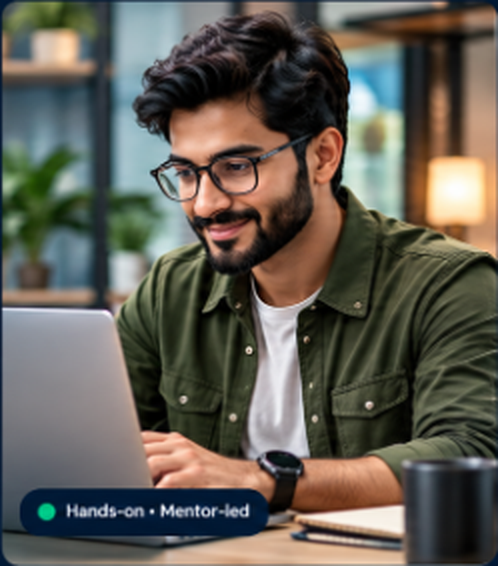
LLM Engineering & RAG (Retrieval-Augmented Generation) Course Student Working on AI Projects
LlamaIndex
LlamaIndex
Pinecone
Pinecone
Qdrant
Qdrant
LangChain
LangChain
ChromaDB
ChromaDB
pgvector
pgvector
Cohere Rerank
Cohere Rerank
FastAPI
FastAPI
๐Ÿ–ฅ๏ธLive Interactive Coding
๐Ÿ‘คAI Principal Mentors
๐Ÿ“‹Enterprise Capstones
๐Ÿ’ผPlacement Assurance

Start Your Career in LLM Engineering & RAG

Get personalized curriculum & free 1-on-1 counseling.
✨
๐Ÿ‘ค
๐Ÿ“ž
โœ‰๏ธ
๐Ÿ“–
Preferred Mode:
100% Confidential. Instant Syllabus PDF Access.
Authorized Training & Certification Partners
Microsoft
IBM
AWS
Google
Oracle
Meta
Adobe
4.9/5
Average Rating
48,500+
Successful Learners
140%
Average Career Growth
500+
Hiring Partners
Live & Interactive
Online / Offline Classes
Principal AI Mentors
(10+ Years Exp)
Real Enterprise
Capstone Projects
Resume Building &
Mock Technical Interviews
Globally Recognized
Certification Guidance
Dedicated 100%
Placement Drives
◆ Enterprise-Aligned Curriculum

Complete LLM Engineering & RAG Curriculum — Foundations to Enterprise Scale

Engineered in collaboration with principal engineers from leading product and Fortune 500 AI teams.

01

RAG Architecture Fundamentals & Document Parsing

⏱ In-Depth Module
โšก
  • Why RAG is Essential: Solving LLM Hallucinations, Knowledge Cutoffs & Data Privacy
  • Advanced Document Parsing: PDF, DOCX, HTML, Tables & Images with LlamaParse & Unstructured
  • Chunking Strategies: Fixed-size, Recursive Character, Semantic & Sentence-Window chunking
02

Embeddings & Vector Database Engineering

⏱ In-Depth Module
โšก
  • Dense vs Sparse Embeddings: OpenAI text-embedding-3, BGE-large, Cohere, BM25
  • Similarity Metrics: Cosine Similarity, Dot Product, Euclidean Distance (L2)
  • Vector Indexing Algorithms: HNSW (Hierarchical Navigable Small World), IVF, Flat
03

Advanced Retrieval Strategies & Hybrid Search

⏱ In-Depth Module
โšก
  • Hybrid Search: Combining BM25 Keyword Search with Dense Vector Search using RRF (Reciprocal Rank Fusion)
  • Query Transformations: HyDE (Hypothetical Document Embeddings) & Multi-Query Generation
  • Parent-Child Indexing: Small chunks for retrieval, large parent contexts for generation
04

Agentic & Graph-Augmented RAG (GraphRAG)

⏱ In-Depth Module
โšก
  • Router Query Engines: Dynamically choosing between multiple indexes, databases, and summaries
  • Sub-Question Query Engines: Breaking complex user questions into multiple parallel sub-retrievals
  • GraphRAG Concepts: Integrating Knowledge Graphs (Neo4j) with Vector Embeddings

Detailed Module-by-Module Breakdown

Click each module below to explore technical topics, coding labs, and tools covered.

Module 01

RAG Architecture Fundamentals & Document Parsing

14 Hours

Understand the naive RAG failure modes and master advanced data ingestion for enterprise unstructured files.

Core Topics & Competencies:

  • โœ” Why RAG is Essential: Solving LLM Hallucinations, Knowledge Cutoffs & Data Privacy
  • โœ” Advanced Document Parsing: PDF, DOCX, HTML, Tables & Images with LlamaParse & Unstructured
  • โœ” Chunking Strategies: Fixed-size, Recursive Character, Semantic & Sentence-Window chunking
  • โœ” Metadata Extraction & Enrichment: Tagging timestamps, authors, sections & document IDs
  • โœ” Benchmarking Chunk Sizes for Optimal Retrieval vs Context Length
๐Ÿ’ป Hands-on Capstone Lab:

Complex Multi-Table PDF Parsing and Semantic Chunking Pipeline with LlamaParse.

LlamaIndexLlamaParseUnstructuredPython 3.11
Module 02

Embeddings & Vector Database Engineering

16 Hours

Dive deep into embedding vector mathematics, high-dimensional similarity metrics, and database indexing.

Core Topics & Competencies:

  • โœ” Dense vs Sparse Embeddings: OpenAI text-embedding-3, BGE-large, Cohere, BM25
  • โœ” Similarity Metrics: Cosine Similarity, Dot Product, Euclidean Distance (L2)
  • โœ” Vector Indexing Algorithms: HNSW (Hierarchical Navigable Small World), IVF, Flat
  • โœ” Managed Vector DBs: Pinecone, Qdrant & ChromaDB setup and CRUD operations
  • โœ” Relational Vector Extensions: PostgreSQL with pgvector for unified transactional + vector storage
  • โœ” Partitioning, Sharding & Multi-Tenant Namespace Isolation
๐Ÿ’ป Hands-on Capstone Lab:

Multi-Tenant Vector Storage Architecture on Qdrant with Metadata Filtering and RBAC.

PineconeQdrantChromaDBpgvectorPostgreSQL
Module 03

Advanced Retrieval Strategies & Hybrid Search

16 Hours

Overcome semantic blind spots with hybrid sparse-dense search, query expansions, and multi-query routing.

Core Topics & Competencies:

  • โœ” Hybrid Search: Combining BM25 Keyword Search with Dense Vector Search using RRF (Reciprocal Rank Fusion)
  • โœ” Query Transformations: HyDE (Hypothetical Document Embeddings) & Multi-Query Generation
  • โœ” Parent-Child Indexing: Small chunks for retrieval, large parent contexts for generation
  • โœ” Self-Querying Retrievers: Natural language translation into vector metadata filters
  • โœ” Sentence-Window Retrieval: Fetching surrounding sentences for precise context
๐Ÿ’ป Hands-on Capstone Lab:

Hybrid Search Engine combining BM25 keyword matching and dense vector embeddings with Reciprocal Rank Fusion.

LlamaIndexLangChainQdrantOpenAI API
Module 04

Re-Ranking, Context Compression & Synthesis

14 Hours

Refine retrieved chunks to maximize relevance and eliminate LLM 'Lost in the Middle' attention degradation.

Core Topics & Competencies:

  • โœ” Re-Ranking Models: Cohere Rerank, BGE-Reranker, Cross-Encoders
  • โœ” Contextual Compression: Pruning irrelevant sentences before passing to context window
  • โœ” Prompt Stuffing vs Map-Reduce vs Refine Synthesis Strategies
  • โœ” Citation & Grounding: Returning exact document page numbers and source URLs with answers
  • โœ” Handling Long Context LLMs: When to use RAG vs 1M+ Token Context Windows
๐Ÿ’ป Hands-on Capstone Lab:

Automated Source Citation & Footnote Grounding Pipeline with Cohere Re-Ranking.

Cohere APICross-EncoderLlamaIndexOpenAI
Module 05

Agentic & Graph-Augmented RAG (GraphRAG)

16 Hours

Level up from single-hop retrieval to multi-hop reasoning, routing agents, and Knowledge Graph integration.

Core Topics & Competencies:

  • โœ” Router Query Engines: Dynamically choosing between multiple indexes, databases, and summaries
  • โœ” Sub-Question Query Engines: Breaking complex user questions into multiple parallel sub-retrievals
  • โœ” GraphRAG Concepts: Integrating Knowledge Graphs (Neo4j) with Vector Embeddings
  • โœ” Entity Extraction and Relationship Mapping for Complex Domain Queries
  • โœ” Agentic RAG Workflows with LangGraph for iterative fact verification
๐Ÿ’ป Hands-on Capstone Lab:

Multi-Hop Financial Equity Research System answering cross-company questions using GraphRAG and Agentic Routing.

Neo4jGraphRAGLangGraphLlamaIndex
Module 06

RAG Evaluation, Observability & Security

14 Hours

Quantitatively evaluate RAG performance, track telemetry, and protect against prompt injection.

Core Topics & Competencies:

  • โœ” RAG Triad: Faithfulness, Answer Relevance, Context Precision & Context Recall
  • โœ” Evaluation Frameworks: Ragas (Retrieval Augmented Generation Assessment) & TruLens
  • โœ” Synthetic Test Dataset Generation using LLMs
  • โœ” Tracing & Telemetry with LangSmith, Arize Phoenix & OpenInference
  • โœ” RAG Security: Preventing Document-Based Indirect Prompt Injections & Data Leakage
๐Ÿ’ป Hands-on Capstone Lab:

Continuous Evaluation CI/CD Pipeline with Ragas scoring and automated quality gates.

RagasTruLensLangSmithPhoenixFastAPI

Tools & Frameworks You Will Master

Gain hands-on proficiency in the exact modern tech stack used across Fortune 500 tech teams.

LlamaIndex
LlamaIndex
Pinecone
Pinecone
Qdrant
Qdrant
LangChain
LangChain
ChromaDB
ChromaDB
pgvector
pgvector
Cohere Rerank
Cohere Rerank
FastAPI
FastAPI
LAUNCHPAD PRO

Build Experience That Gets You Interview-Ready

Real project work. Agile exposure. Mentor feedback. A portfolio you can talk about in interviews.

Live Project Work
Agile + Jira Workflow
Team Collaboration
Mentor Code &
Project Reviews
Resume + Interview
Prep
Completion Certificate
LaunchPad Pro Student Experience
Hands-on • Mentor-led

Already trained. Now build proof of your skills.

Turn learning into practical experience you can discuss with confidence.

  • Work on live enterprise projects
  • Build a real-world portfolio
  • Use Agile workflows & Jira
  • Get mentor feedback
  • Practice with mock interviews
Designed for job-focused learners
48,500+
Successful Learners
500+
Hiring Partners
โ‚น12.5 LPA
Highest Package
140%
Average Career Growth
100%
Interview Guarantee

Career & Salary Calculator

Explore verified 2026 compensation benchmarks and market demand curves across India's top tech hubs.

๐Ÿ’ฐ Estimated Salary Range
Market Data 2026
₹ 8.5 LPA – 16.5 LPA
Frontier AI Specialist | 1-3 Years | Delhi NCR
๐Ÿ“ˆEntry Level
₹ 7.5 – 9.5 LPA
๐Ÿ’ผMid Level
₹ 11.0 – 16.5 LPA
โญLead Architect
₹ 25.0+ LPA

Based on verified 2026 hiring data from Fortune 500 and Top MNC tech recruiters.

Salary Curve by Experience
High-Paying Frontier Track
7.5L
Fresher
12.5L
1 - 3 Yrs
18.5L
3 - 5 Yrs
28.0L
5 - 8 Yrs
42.0L+
8+ Yrs

Frequently Asked Questions

Everything you need to know about the LLM Engineering & RAG (Retrieval-Augmented Generation) Course, batches, prerequisites & placement assurance.

Why is RAG currently one of the highest paid skills in AI engineering?

Enterprises have massive troves of proprietary documents (contracts, manuals, customer databases) that public LLMs cannot access. Fine-tuning is expensive, slow to update, and prone to hallucinations. RAG allows companies to ground LLMs in their exact private data in real time, making RAG engineers indispensable across MNCs and startups.

What is the difference between LlamaIndex and LangChain for RAG?

LangChain is a general-purpose orchestration framework for building chains and agents. LlamaIndex is purpose-built and hyper-specialized for data ingestion, indexing, and advanced RAG retrieval patterns. In this course, you will learn to use both frameworks together for production architectures.

Will we learn Hybrid Search and Re-Ranking?

Yes! Naive vector search misses exact keyword matches (like part numbers, names, codes). You will build production-grade Hybrid Search combining BM25 keyword matching with dense vectors and Cohere Re-Ranking.